
Author’s note: This article breaks down the blind test, appendix benchmarks, and product-side testimonials from Tencent’s research page. It compares Hy4 flash and GLM-5.3-Flash across everyday tasks, terminal coding, cost, and integration protocols, and explains which one you can call today on APIYI.
Tencent Hunyuan released Hy4 flash on 2026-11-16, positioning it officially as “the cheapest model for everyday productivity.” Plenty of people are now choosing between GLM-5.3-Flash and it as their daily driver. Tencent’s research page offers three kinds of material: human blind tests, appendix benchmark tables, and product-side testimonials. The conclusions from these three sources don’t line up perfectly.
This isn’t a “both have their merits” compromise piece. Below, the three sets of data are laid out separately, with a source noted for every number. At the end, you get a clear choice by scenario — plus which model you can call directly on APIYI today.
Core value: By the end of this article, you’ll know where Hy4 flash wins in the blind test, where GLM-5.3-Flash wins in the appendix benchmarks, and the protocol and pricing details to watch out for when integrating.
Hy4 flash vs GLM 5.3 Flash: the core differences
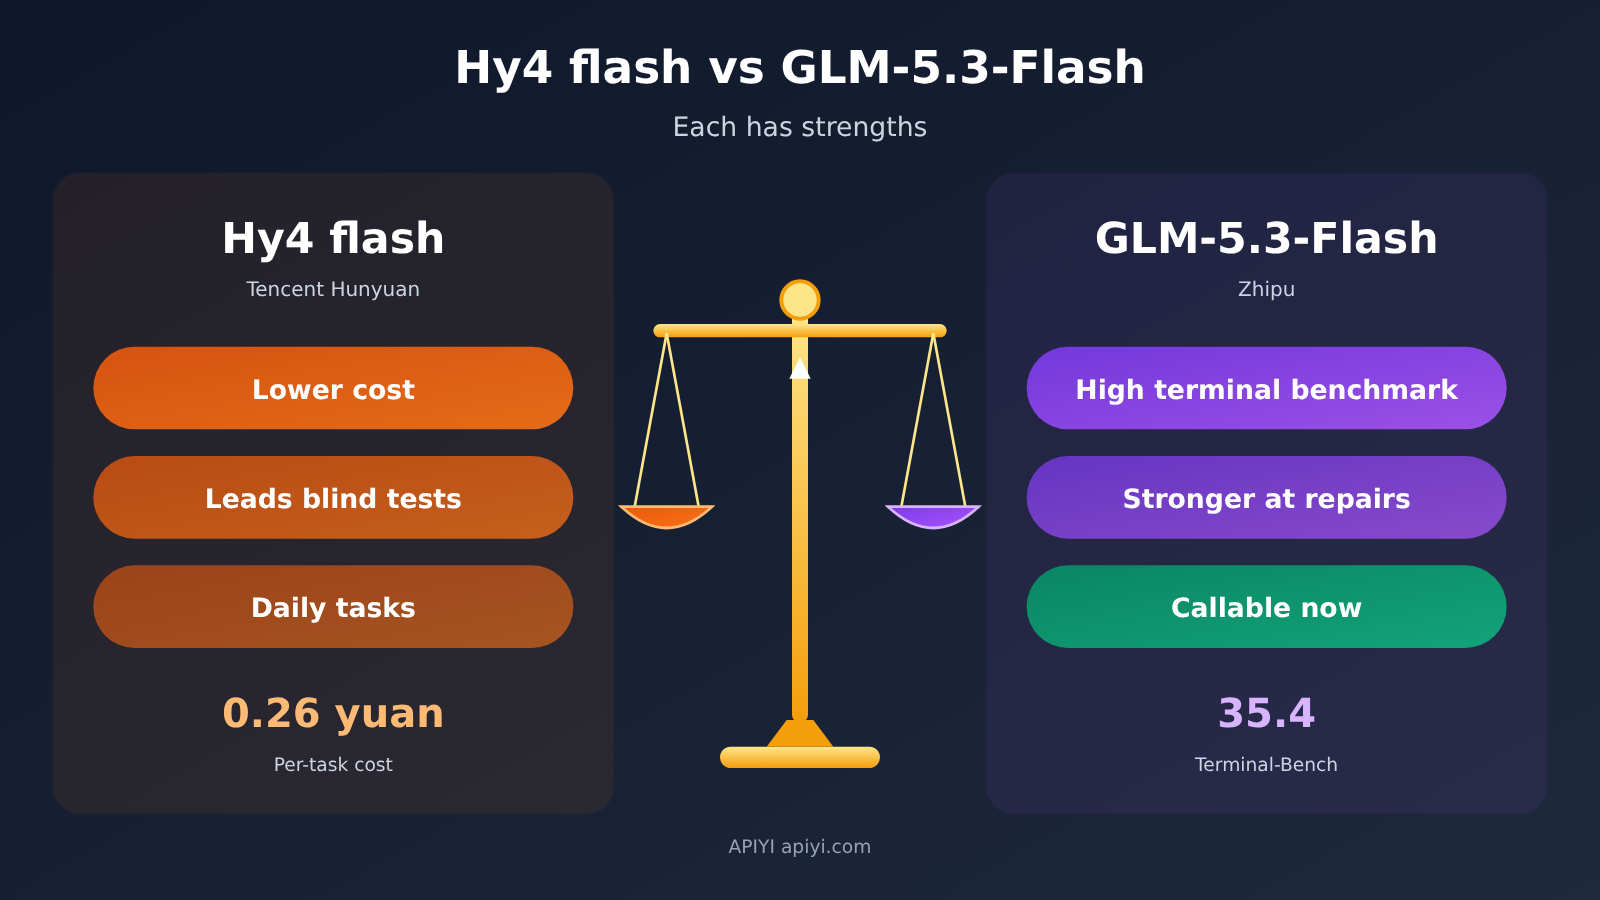
Let’s start with the bottom line: neither model wins across the board. In Tencent’s blind test, Hy4 flash scored higher on satisfaction and was faster and cheaper. In the appendix results for things like Terminal-Bench 4.0 and PPTFixBench — benchmarks that lean toward “repair work” and terminal operations — GLM-5.3-Flash scored higher.
| Comparison | Hy4 flash | GLM-5.3-Flash | Data source |
|---|---|---|---|
| Blind-test satisfaction (4-point scale) | 2.79 | 2.53 | Tencent research page blind-test table (self-reported) |
| Median end-to-end time | 6.7 minutes | 7.6 minutes | Same as above |
| Blind-test cost per task | ¥0.26 | ¥0.81 | Same as above, RMB |
| Terminal-Bench 4.0 | 19.2 | 35.4 | Tencent research page appendix |
| PPTFixBench | 23.7 | 28.6 | Tencent research page appendix |
| MdCoEditBench (Markdown co-writing) | 56.9 | 32.3 | Tencent research page appendix |
| Specs | 224B total parameters (including 64B Engram), 12B active, 1M context | 320B total parameters, 18B active, 1M context, max output 128,000 | Research page / APIYI model page |
| Available platforms | Tencent Cloud TokenHub, WorkBuddy, etc.; not yet listed on APIYI | Already listed on APIYI apiyi.com as glm-5.3-flash |
Research page / APIYI model list |
Every score in this table comes from Tencent. GLM never got a turn to defend itself. Keep that in mind as you read: both the blind test and the appendix are self-reported by Tencent, and most of the eval sets are Tencent’s internal ones — these aren’t public leaderboard rankings.
Three different data framings behind the Hy4 flash vs GLM 5.3 Flash comparison
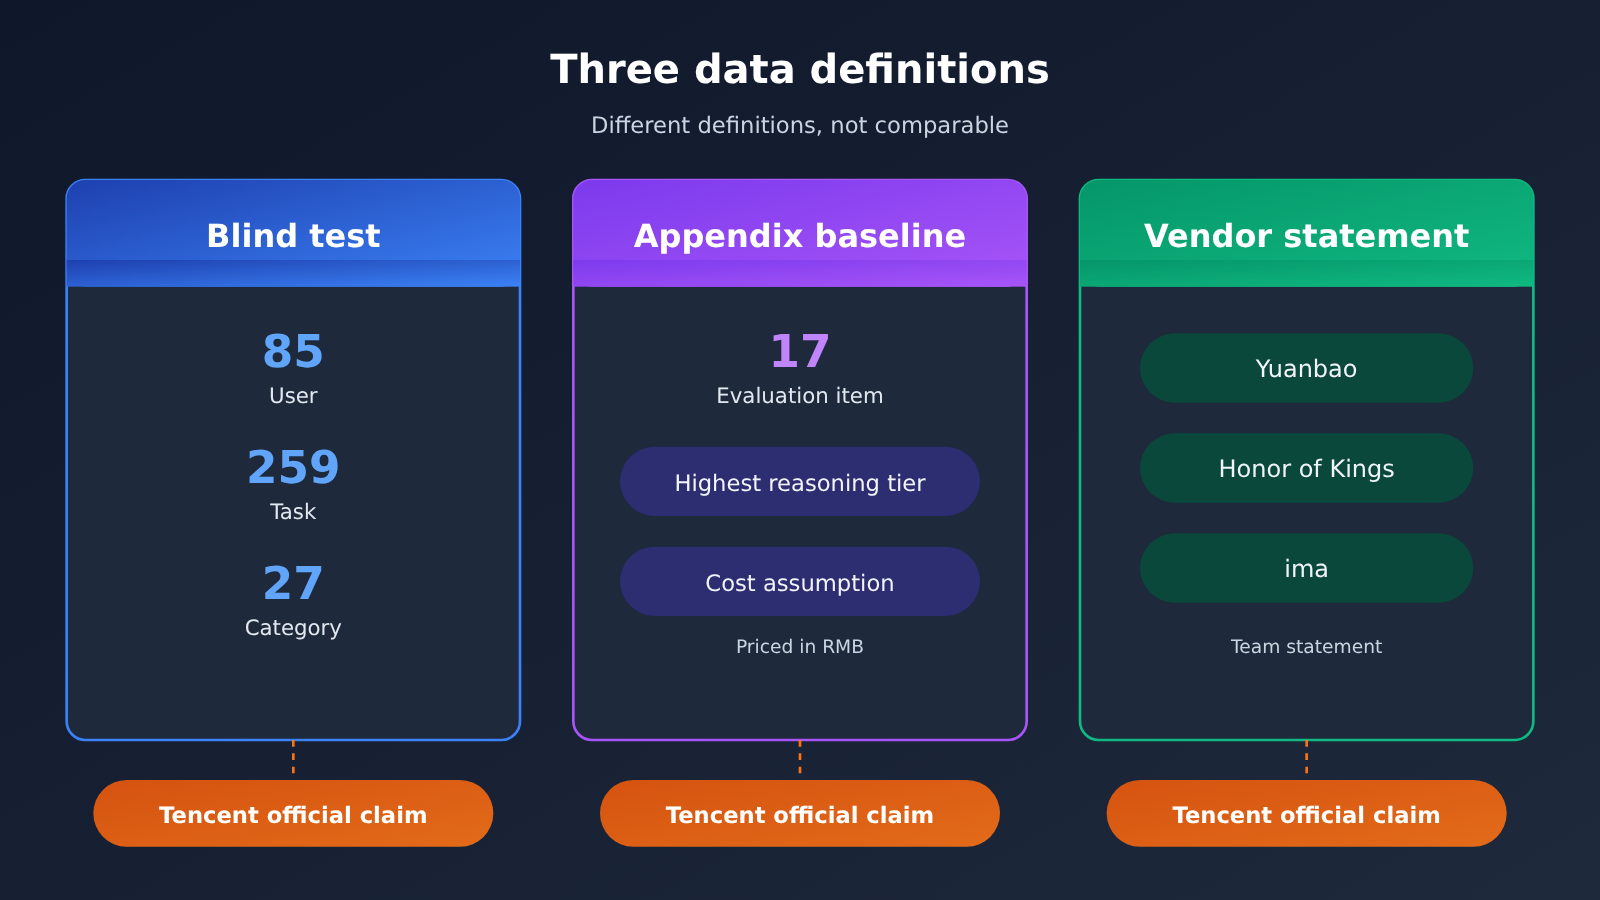
These three sets of materials use completely different framings, and mixing them together is an easy way to draw the wrong conclusion:
- Blind test: 85 internal WorkBuddy users, 259 tasks, 27 categories. External models (GLM included) ran at the high setting; the Hy4 flash row doesn’t specify a setting.
- Appendix table: 17 benchmark items, with every model at its own highest reasoning setting. Each cell also lists a per-task cost, calculated at Tencent’s own fixed RMB prices.
- Testimonials from product teams: self-reported numbers from teams like Yuanbao, Honor of Kings, and ima — each with its own scenario and its own baseline, so they can’t be stitched together into a cross-comparison.
Hy4 flash vs. GLM 5.3 Flash Blind Test Results
The blind test is the most favorable piece of evidence for Hy4 flash. The full blind-test table on the research page has four rows, reproduced as-is below (Tencent’s own reported figures):
| Model | Satisfaction (4-point scale) | Median end-to-end time | Cost per task (RMB) |
|---|---|---|---|
| DeepSeek-V4.1-Flash-1017 (high) | 3.09 | 10.3 min | RMB 1.20 |
| Hy4 flash (tier not specified) | 2.79 | 6.7 min | RMB 0.26 |
| Claude-Haiku-5.5 (high) | 2.81 | 6.8 min | RMB 4.73 |
| GLM-5.3-Flash (high) | 2.53 | 7.6 min | RMB 0.81 |
Looking only at the Hy4 flash and GLM-5.3-Flash rows, Hy4 flash has 0.26 points higher satisfaction, is about 0.9 minutes faster, and costs about one-third as much per task as GLM. This directly backs up the claim that it’s cheaper in everyday blind tests.
There are three points to read carefully. First, the highest satisfaction score belongs to DeepSeek at 3.09, not Hy4 flash. Second, Hy4 flash is 0.02 points below Haiku. The research page says “close to,” not “surpasses.” Third, the “18x task cost reduction” in the official post comes from dividing RMB 4.73 by RMB 0.26. The comparison is against Haiku, not GLM.
How the blind-test costs for Hy4 flash vs. GLM 5.3 Flash were calculated
The RMB costs in the blind-test table were calculated by Tencent using its own pricing methodology. They reflect “who spends less on the same set of tasks,” not your actual bill on any platform. Hy4 flash’s low cost comes partly from a low list price and partly from what the research page says: reinforcement learning cut average end-to-end output tokens by 50%.
The research page also has a set of WorkIndex findings: the average cost per task is 1/13 that of Hy4 preview and 1/20 that of Hy4. These statements apply only to WorkIndex. Don’t use them to replace the RMB figures in the blind-test table, and they have nothing to do with GLM.
Hy4 flash vs. GLM-5.3-Flash: Appendix Benchmarks
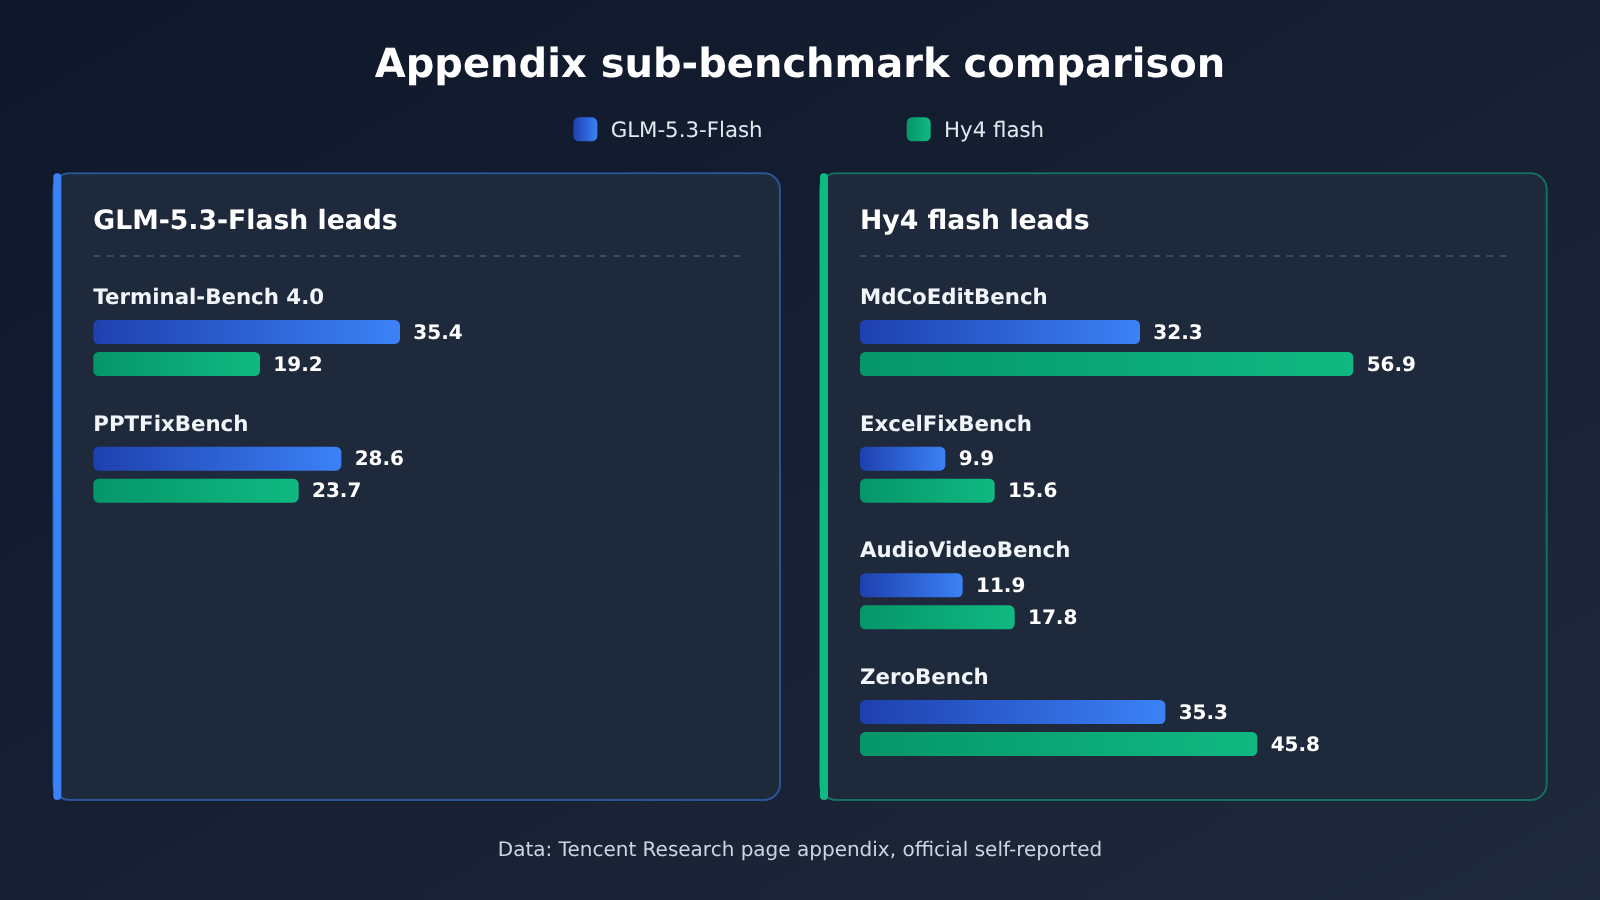
The appendix is where GLM-5.3-Flash makes its comeback. The table below is transcribed from the full chart in the Appendix on Tencent’s research page, keeping only the two model columns. Each cell is formatted as “score / per-task cost (RMB)”:
| Benchmark | Hy4 flash | GLM-5.3-Flash | Higher score |
|---|---|---|---|
| PPTGenBench | 54.2 / 0.169 | 53.6 / 1.460 | Hy4 flash |
| PPTCoEditBench | 74.0 / 0.105 | 67.3 / 0.489 | Hy4 flash |
| PPTFixBench | 23.7 / 0.253 | 28.6 / 2.517 | GLM |
| MdCoEditBench | 56.9 / 0.057 | 32.3 / 0.133 | Hy4 flash |
| WordEditBench | 46.2 / 0.629 | 47.6 / 2.840 | GLM |
| ExcelFixBench | 15.6 / 0.310 | 9.9 / 2.879 | Hy4 flash |
| AudioVideoBench | 17.8 / 0.344 | 11.9 / 3.370 | Hy4 flash |
| BuddyVQA Atlas (no tools) | 48.5 / 0.007 | 50.1 / 0.019 | GLM |
| DeepSWE v1.1 | 64.6 / 0.290 | 67.8 / 3.230 | GLM |
| ProgramBench | 16.0 / 0.561 | 13.0 / 17.959 | Hy4 flash |
| Terminal-Bench 4.0 | 19.2 / 0.558 | 35.4 / 5.597 | GLM |
| APEX-Agents v1.1 | 63.1 / 0.087 | 51.5 / 0.485 | Hy4 flash |
| AutomationBench v1.0.6 | 52.2 / 0.038 | 48.4 / 0.104 | Hy4 flash |
| HLE-Full (with tools) | 55.2 / 0.060 | 52.2 / 0.616 | Hy4 flash |
| OSWorld 2.1 | 68.1 / 0.451 | 64.0 / 3.803 | Hy4 flash |
| MMMU-Pro | 75.8 / 0.010 | 77.0 / 0.013 | GLM |
| ZeroBench-main (with tools) | 45.8 / 0.077 | 35.3 / 1.861 | Hy4 flash |
The biggest gap is Terminal-Bench 4.0: GLM scores 35.4 vs. Hy4 flash’s 19.2 — nearly double. This benchmark uses the Claude Code harness, with up to 500 turns and a maximum of 13 hours per run, and tests long-horizon terminal operations. GLM also leads PPTFixBench by about 5 points. GLM is slightly ahead on DeepSWE, WordEditBench, BuddyVQA, and MMMU-Pro as well.
Hy4 flash pulls ahead on Markdown co-writing (56.9 vs. 32.3), spreadsheet repair, audio/video processing, and ZeroBench. These tasks are closer to everyday office work — writing documents, fixing tables, and working with media assets. This aligns with the recommendation on the research page: for long-horizon software engineering, keep using Hy4, not Hy4 flash.
The cost column in the appendix is Tencent’s assumption, not a platform bill
The appendix states that costs are based on each model’s official API pricing, with 1 USD converted at 7.2 RMB. For GLM-5.3-Flash it uses a fixed price of 0.8 yuan per million input tokens, 0.23 yuan for cache hits, and 2.8 yuan for output, labeled “standard API price.” These are the appendix assumptions Tencent used when building the table — they aren’t APIYI’s listed prices, and you shouldn’t use them to convert your APIYI bill.
Hy4 flash vs GLM 5.3 Flash: what the product teams said
The research page also includes testimonials from Tencent’s various product teams, and three of them call out GLM-5.3-Flash by name. All of these are the product teams describing their own results, and each one uses a different scenario and baseline:
- Yuanbao (product team’s own account): general conversation scored 2.52% higher than GLM-5.3-Flash, with the gap most obvious on multi-turn dialogue. This is Yuanbao’s internal evaluation, not a public leaderboard.
- Honor of Kings (product team’s own account): root-cause localization was comparable to DeepSeek-V4.1-Flash-1017 and GLM-5.3-Flash. The model made 22.0% to 39.1% fewer requests, used 40.5% to 61.2% fewer tokens, and made 51.2% and 7.7% more tool calls, respectively.
- ima (product team’s own account): compared with those two models, average wait time was 18% to 35% shorter, reply scores were 1.8% higher, and content quality was 8.1% higher.
What these have in common: Hy4 flash wins on “spending fewer tokens and waiting less,” while on quality it’s roughly on par or slightly ahead. They support the blind-test conclusions, but they can’t refute the Terminal-Bench gap in the appendix — it’s simply not the same kind of task.
Hy4 flash vs. GLM 5.3 Flash: Pricing and Access
Pricing is the easiest place to get things wrong. Numbers from different sources shouldn’t be mixed, so the table below separates where each price comes from (all figures in USD per million tokens):
| Model / Source | Input | Output | Cache read | Notes |
|---|---|---|---|---|
| Hy4 flash (Tencent research page list price) | 0.070 | 0.281 | 0.003 | Not the APIYI list price; 50% off on TokenHub through 2026-11-30 |
glm-5.3-flash (APIYI apiyi.com model page) |
0.15 | 0.50 | 0.03 | Already listed; groups CodexResponses, Default, SVIP; multiplier 1x |
glm-5-3-flash-260828 (APIYI master table) |
0.15 | 0.499995 | 0.03 | Another channel; doesn’t conflict with the row above |
hy4 (APIYI master table) |
0.85 | 2.55 | 0.045 | This is Hy4, not Hy4 flash |
| Hy4 (Tencent research page list price) | 0.834 | 2.501 | 0.042 | Research page list price; keep it separate from APIYI pricing |
Hy4 flash’s 50% discount is a limited-time window price on TokenHub. The research page doesn’t publish a separate discounted price table, so if you divide by 2 yourself to estimate, remember that list prices return after November 30.
Hy4 flash isn’t listed yet — we’ll get it up as soon as we can. Model names and prices are subject to the platform’s model list. Right now APIYI only has hy4; there’s no flash version of Hunyuan at all. If what you need is the high-ceiling version of Tencent Hunyuan, you can start with hy4; if what you want is specifically Hy4 flash, then at this stage you can only go through official channels like Tencent Cloud TokenHub and WorkBuddy. The research page also doesn’t give an API model ID, so before you call it, go by the name shown in the TokenHub console.
How to Call GLM-5.3-Flash on APIYI
glm-5.3-flash is callable today. On APIYI it only supports OpenAI Chat Completions — not Anthropic Messages, and not Responses. That’s what determines whether you can plug it straight into certain clients:
- Create a key in the apiyi.com console.
- Set the client’s base_url to
https://api.apiyi.com/v1; the request path is/chat/completions. - In the request body, set
modeltoglm-5.3-flashand passmessagesin OpenAI format. - Thinking is on by default; input can be text, images, or video, and output is text.
If your tool only sends Anthropic Messages-format requests, you can’t use glm-5.3-flash directly. In those cases, either switch to a client that supports Chat Completions, or use a model that offers both chat and messages endpoints. Context, max output, endpoints, and other parameters are subject to the APIYI model page.
🚀 Integration tip: For models already listed on APIYI, use your apiyi.com key and send requests to
https://api.apiyi.com/v1— with an OpenAI-compatible client, you only need to change two config settings and you’re up and running. New users get free test credit, so you can tryglm-5.3-flashon your everyday tasks first.
Hy4 flash vs GLM 5.3 Flash: Scenario Recommendations
When to choose Hy4 flash
- Document and Markdown co-editing: Appendix MdCoEditBench comes in at 56.9 vs 32.3 — a clear gap.
- Table repair and audio/video material processing: Hy4 flash leads on both ExcelFixBench and AudioVideoBench.
- Cost-sensitive, high-frequency everyday tasks: blind testing puts it at 0.26 yuan vs 0.81 yuan per task (Tencent’s own figures).
- Multi-turn conversational products: the Yuanbao product team reports a 2.52% edge on general chat, with multi-turn being the most pronounced.
When to choose GLM-5.3-Flash
- Terminal operations and long-horizon command-line tasks: Terminal-Bench 4.0 lands at 35.4 vs 19.2 — the widest gap of the whole comparison.
- Slide repair tasks: PPTFixBench at 28.6 vs 23.7.
- You need to ship today:
glm-5.3-flashis already live on APIYI; Hy4 flash isn’t yet. - Your toolchain is built on Chat Completions: OpenAI-format clients can plug straight in.
Hy4 flash vs GLM 5.3 Flash: Decision Guide
| Your situation | Recommendation |
|---|---|
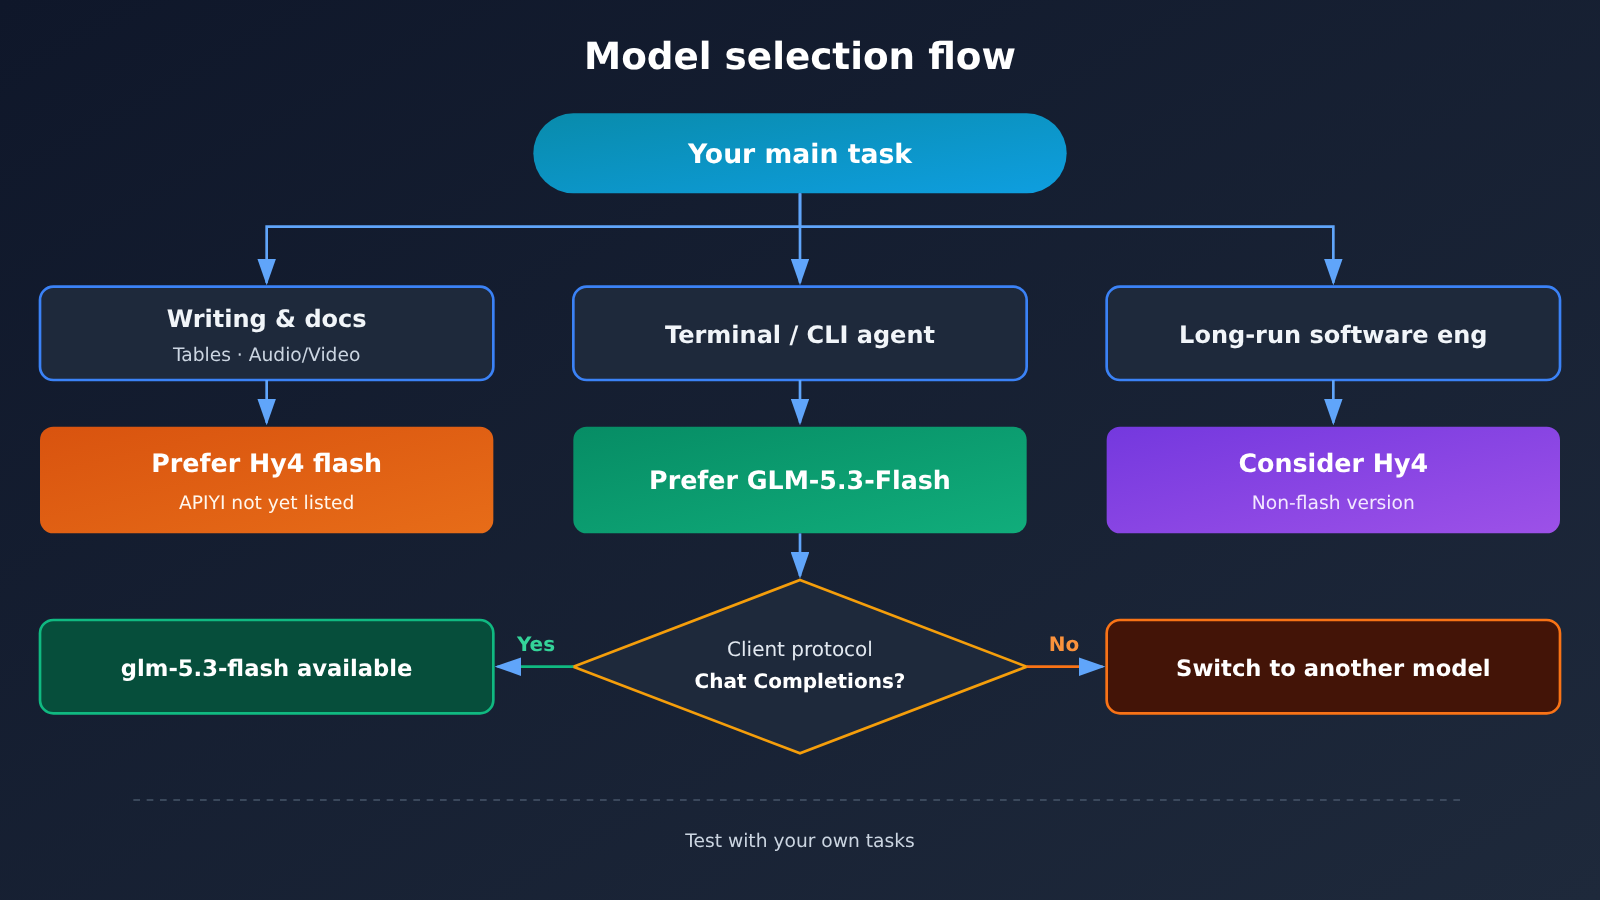
| Mostly writing, documents, tables, material processing | Wait for Hy4 flash to be listed, or try Tencent’s official channel first |
| Mostly terminal operations and command-line agents | Choose GLM-5.3-Flash |
| You need it live on APIYI today | Choose glm-5.3-flash via Chat Completions |
| Client only supports Anthropic Messages | glm-5.3-flash doesn’t apply — switch to a model that supports messages |
| Long-horizon software engineering | Neither is the first pick; the research page recommends Hy4 |
💡 Recommendation: The blind test and the appendix point in different directions, so the safest approach is to run a batch of your own tasks through each. You can validate
glm-5.3-flashon APIYI at apiyi.com right now; once Hy4 flash is listed, just swap themodelparameter and compare both within the same codebase.
FAQ
Q1: What are Hy4 flash and GLM-5.3-Flash?
Hy4 flash is an everyday-task model released by Tencent Hunyuan on 2026-11-16, with 224B total parameters, 12B active, and a 1M context window. According to its model page on APIYI, GLM-5.3-Flash has 320B total parameters, 18B active, and a 1M context window; the vendor released it on 2026-08-26.
Q2: Hy4 flash vs. GLM 5.3 Flash — which one is actually stronger?
It depends on the task type. In Tencent’s blind test, Hy4 flash scored 2.79 on satisfaction versus 2.53 for GLM. In the appendix, GLM comes out higher on Terminal-Bench 4.0 and PPTFixBench, while Hy4 flash leads on Markdown co-writing, tables, audio/video, and ZeroBench. All of that data is self-reported by Tencent.
Q3: Yuanbao says general chat is 2.52% higher than GLM-5.3-Flash — is that credible?
That’s a self-reported evaluation from the Yuanbao product team, not a public leaderboard, and the methodology details aren’t public. You can treat it as a hint that Hy4 flash may have an edge in multi-turn conversation, but it shouldn’t be taken as a settled conclusion.
Q4: Are the 0.8 yuan, 0.23 yuan, and 2.8 yuan figures for GLM in the appendix APIYI’s prices?
No. Those are fixed RMB price assumptions Tencent used when building the appendix table. On APIYI’s model page, `glm-5.3-flash` is priced at $0.15 input, $0.50 output, and $0.03 cached read per million tokens — always check the platform’s model list for the authoritative numbers.
Q5: Can I call Hy4 flash on APIYI right now?
Hy4 flash isn’t listed yet, and we’ll get it up as soon as we can; model IDs and pricing follow the platform’s model list. What you can call on APIYI today is `glm-5.3-flash` and `hy4` — note that `hy4` is not the flash version. You can follow new listings on the model list at apiyi.com.
Q6: Can glm-5.3-flash be used with a client that only supports the Anthropic format?
No. On APIYI, `glm-5.3-flash` only exposes the OpenAI Chat Completions endpoint; it doesn’t support Messages or Responses. Your client needs to be able to point `base_url` at `/v1` and send Chat Completions requests.
Q7: What are the known weaknesses of the two models?
Hy4 flash scores only 19.2 on Terminal-Bench 4.0, and the research page itself admits it trails Hy4 on long-horizon software engineering; its weights are currently only planned for open-sourcing. GLM-5.3-Flash lags in blind-test satisfaction and Markdown co-writing, and it’s Chat Completions only. Note that the comparison data for both comes from Tencent.
Hy4 flash vs GLM 5.3 Flash: Key Takeaways
- Hy4 flash wins the blind test: satisfaction 2.79 vs. 2.53, 6.7 minutes vs. 7.6 minutes, ¥0.26 vs. ¥0.81.
- GLM scores higher on terminal benchmarks: Terminal-Bench 4.0 comes in at 35.4 vs. 19.2, and GLM also leads on PPTFixBench.
- Hy4 flash scores higher on everyday office tasks: bigger numbers on Markdown co-writing, table repair, audio/video, and ZeroBench.
- Testimonials are just self-reports: Yuanbao’s “2.52% higher” is the vendor’s own claim, not a public leaderboard.
- Keep the price sources straight: the RMB figures in the appendix are Tencent’s assumptions, and the USD figures on the research page are list prices — neither is APIYI’s listed price.
- The one you can call today is GLM:
glm-5.3-flashis already live on APIYI (apiyi.com), and it only supports Chat Completions.
Summary
The core conclusions from comparing Hy4 flash with GLM 5.3 Flash:
- For everyday tasks, look at Hy4 flash: in Tencent’s blind test it’s more satisfying, faster, and cheaper, and it also scores higher on document and table benchmarks.
- For terminal tasks, look at GLM-5.3-Flash: the Terminal-Bench 4.0 gap is nearly two-fold, so long-running command-line tasks shouldn’t go to Hy4 flash.
- For real deployment, look at availability and protocol: the model you can call on APIYI today is
glm-5.3-flash, and it only uses Chat Completions; Hy4 flash isn’t listed yet.
If your work is mostly writing and documentation, keep an eye on when Hy4 flash becomes available; if you lean toward terminal work or need to ship right away, glm-5.3-flash is the more direct choice. I’d recommend using the free trial credits on apiyi.com, running a round with your own real tasks, and then deciding.
📚 References
-
Tencent Hunyuan Hy4 flash research page: blind test tables, appendix benchmarks, product-side testimonials, and list prices
- Link:
hy.tencent.ai/research/hy4-flash - Notes: All blind tests, appendix scores, and testimonials in this article come from this page and are Tencent’s own self-reported data
- Link:
-
Tencent Hunyuan official release post: Hy4 flash launch and API list prices
- Link:
x.com/TencentHunyuan/status/2122217770314301469 - Notes: This is the source of the “18x task cost reduction” claim; the comparison point is Claude Haiku 5.5
- Link:
-
APIYI GLM-5.3-Flash model page: parameters, context, endpoints, and pricing
- Link:
docs.apiyi.com/models/glm-5-3-flash - Notes: The specs and protocols for
glm-5.3-flashare governed by this page
- Link:
Author: APIYI Technical Team
Technical discussion: Feel free to reach us through the APIYI website homepage. For more models and integration guides, visit the docs.apiyi.com documentation center.


